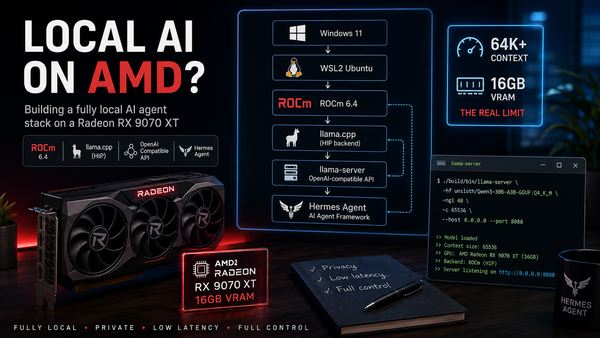
Running a Local AI Agent on AMD: ROCm, WSL2, llama.cpp and Hermes Agent
Update: 64K Context + MTP at Almost 50 Tokens/s
This update was added on August 26, 2026. The original article continues below.
After updating llama.cpp to version 0.3.0-dev build 10640 and experimenting